1. Introduction: When Valid Requests Become a Denial-of-Service Attack
A web application receives thousands of requests every minute. Users browse pages, submit forms, authenticate, and interact with APIs. Under normal conditions, the application processes these requests and returns responses.
Now imagine that request volumes suddenly increase beyond the application's capacity. Web servers begin accumulating requests, database queries take longer to complete, and legitimate users experience timeouts. The network connection remains active, but the application becomes increasingly unresponsive.
This is a common scenario associated with an HTTP flood attack.
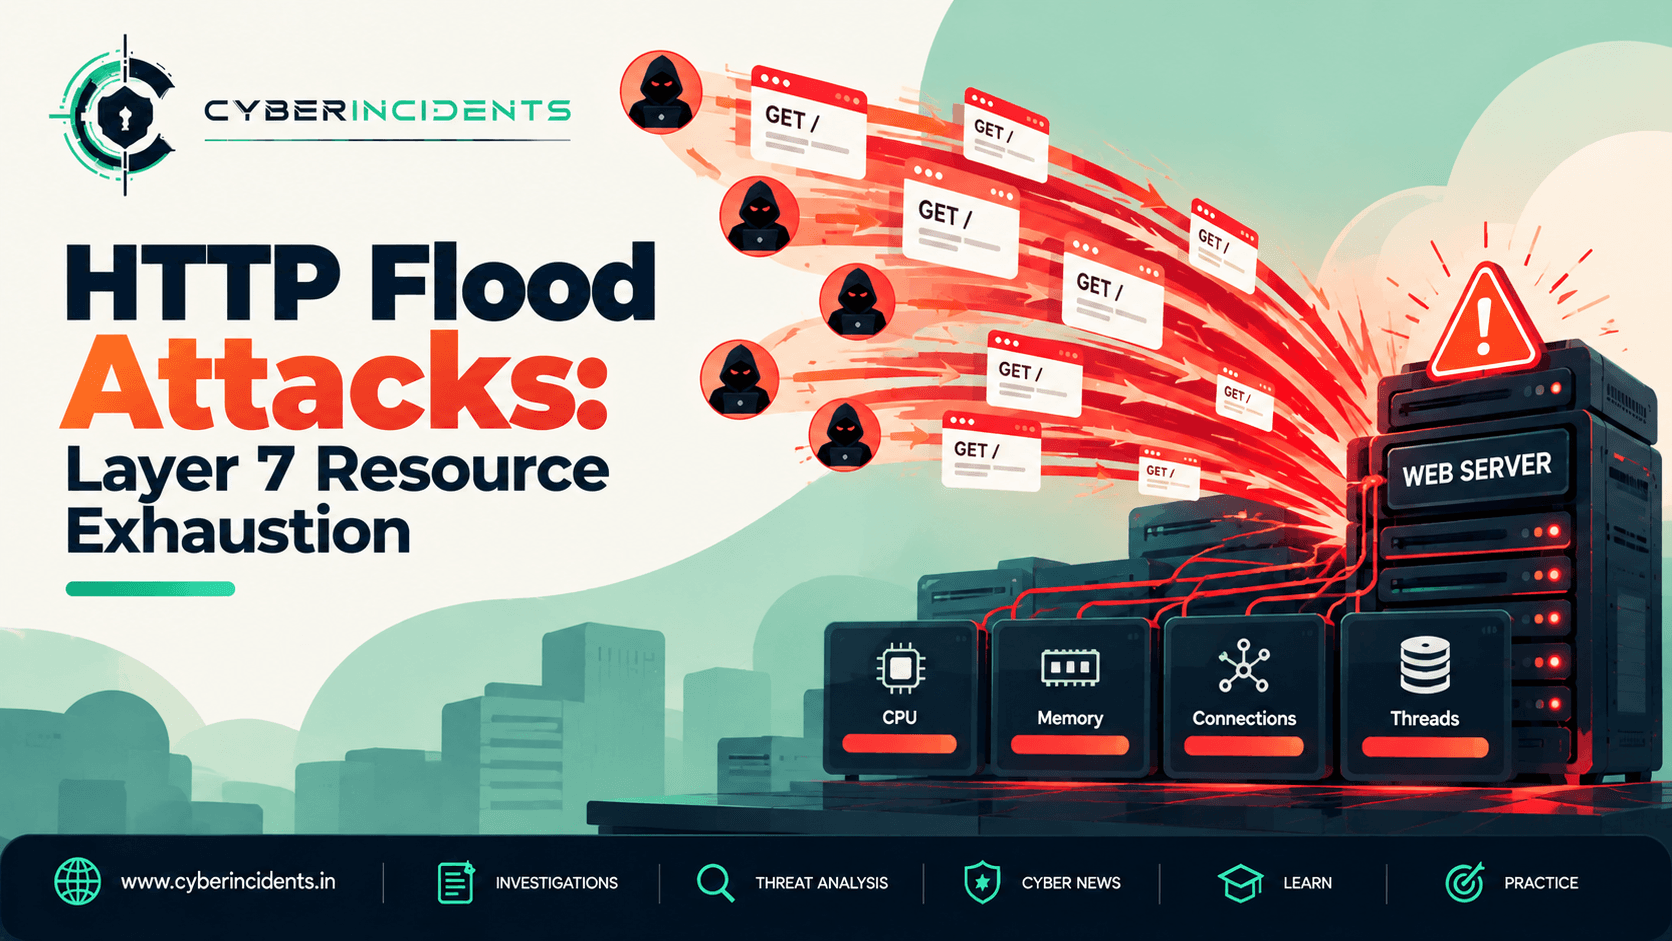
HTTP floods target the application layer, commonly referred to as Layer 7 of the OSI model. Instead of relying exclusively on enormous volumes of raw network traffic, attackers generate requests that consume the resources required to process web transactions.
Some requests may be simple and inexpensive. Others may trigger authentication workflows, database queries, searches, or other computationally expensive operations.
The critical issue is the relationship between the work required to process incoming requests and the resources available to handle them.
For SOC analysts, the challenge is to determine whether the increase represents legitimate demand, a software malfunction, automated scraping, or a deliberate denial-of-service attack.
2. What Is an HTTP Flood Attack?
An HTTP flood is a denial-of-service technique in which an attacker generates excessive HTTP requests to degrade or disrupt an application or its supporting infrastructure.
The attack may target a website, an API, an authentication endpoint, a search function, or another publicly accessible service.
HTTP floods are commonly associated with distributed attacks, where traffic originates from multiple systems. However, an HTTP flood can also originate from a smaller number of sources.
Unlike some network-layer attacks, HTTP floods can use syntactically valid requests and follow normal application protocols. This makes them more difficult to distinguish from legitimate traffic using packet volume alone.
Common HTTP flood patterns
Page-request floods: Excessive requests to web pages or other frequently accessed resources.
API request floods: Large numbers of requests directed at application programming interfaces.
Expensive-endpoint floods: Requests that trigger costly searches, report generation, or database operations.
Authentication floods: Excessive requests to login or authentication services, potentially exhausting application resources.
Distributed HTTP floods: Requests generated from many clients, making simple source-based filtering less effective.
These patterns can overlap. An attacker may target several endpoints or change the traffic pattern as defensive controls are introduced.
An important distinction is that an HTTP flood is not automatically a credential attack simply because it targets a login page. The investigation must establish whether the objective is resource exhaustion, credential guessing, account abuse, or another form of activity.
3. Why HTTP Floods Exhaust Application Resources
Every request requires some amount of processing. Depending on the application, this can involve network handling, request parsing, authentication, business logic, database access, cache lookups, and response generation.
If the request rate exceeds the service's sustainable processing capacity, queues grow and latency increases.
Several resources may become bottlenecks.
CPU exhaustion
Requests can consume CPU time through application logic, encryption, parsing, computation, or repeated processing.
When processing demand exceeds available CPU capacity, requests take longer to complete and fewer requests can be handled per second.
Memory pressure
Applications may allocate memory for request processing, sessions, response generation, or queued work. Excessive concurrency can increase memory consumption and potentially trigger garbage collection pressure, swapping, or process failures.
Worker and thread exhaustion
Web servers and application frameworks often use worker processes, threads, or other execution resources to handle requests.
If too many requests occupy these resources, new requests may wait in queues or be rejected.
Database connection exhaustion
Some endpoints require database access. A high request rate can consume database connections, increase query concurrency, and cause connection pools to reach their limits.
Even when the web server remains operational, the application may become unavailable because its database or another dependency cannot keep up.
Cache bypass and expensive operations
Requests that repeatedly require uncached data or costly operations can increase backend demand.
If the application performs substantial work for each request, relatively modest traffic volumes may cause significant performance degradation.
Key principle: The impact of an HTTP flood depends not only on how many requests arrive, but also on how much work each request triggers.
4. How HTTP Flood Attacks Work
A typical HTTP flood incident can be understood through several stages.
Stage 1: Target selection
The attacker selects a publicly accessible application, API, or endpoint. The target may be a landing page, search function, authentication service, or backend operation.
Stage 2: Request generation
The attacker generates a high volume of HTTP requests. Traffic may originate from automated clients, compromised devices, or distributed infrastructure.
The requests may use valid HTTP methods and headers, making protocol validation alone insufficient to distinguish malicious activity.
Stage 3: Resource consumption
The application processes incoming requests. As demand increases, CPU utilisation, worker occupancy, database connections, or request queues may rise.
Stage 4: Service degradation
Legitimate users experience longer response times, increased HTTP errors, failed transactions, or timeouts.
Depending on the architecture, the bottleneck may occur at a CDN, reverse proxy, web server, application process, or backend dependency.
Stage 5: Continued pressure or changing patterns
The traffic may remain concentrated on one endpoint or shift to other parts of the application. Defensive controls may reduce some traffic while other requests continue to consume resources.
Investigators should avoid assuming that every incident follows this exact sequence. Real attacks differ in duration, distribution, request characteristics, and impact.
5. HTTP Floods vs. Network-Layer DDoS Attacks
Understanding the difference between application-layer and network-layer attacks helps analysts select the right telemetry and mitigation.
FeatureNetwork-layer DDoSHTTP floodPrimary targetNetwork capacity or protocol-processing resourcesApplication and backend resourcesCommon indicatorsHigh bandwidth, packet rates, or connection-state pressureHigh request rates, latency, and application resource useTraffic characteristicsMay involve large volumes of packets or protocol-specific trafficMay consist of valid HTTP requestsMain telemetryNetFlow, packet captures, firewall and interface metricsWeb logs, API telemetry, WAF, application monitoringTypical bottlenecksLink capacity, packet processing, connection stateCPU, workers, database pools, application dependenciesUseful mitigationsUpstream filtering, traffic scrubbing, network controlsCDN protection, WAF, rate limiting, caching, application optimisation
These categories are not mutually exclusive. A multi-vector DDoS attack may combine network-layer floods with HTTP floods.
A service can also experience application-layer exhaustion without saturating its internet connection. This is why bandwidth monitoring alone is insufficient.
6. Detecting HTTP Floods Through Application Telemetry
The most useful indicators often come from web server, API gateway, WAF, and application monitoring systems.
Request-rate anomalies
A sudden increase in requests to a particular endpoint may indicate a flood.
However, high traffic can also result from legitimate product launches, news events, scheduled integrations, or automated clients. Compare the observed request rate with historical baselines and expected business activity.
Elevated response times
Monitor average latency alongside percentile measurements such as p95 and p99 response times.
A sharp increase in tail latency can indicate that some requests are waiting much longer than normal, even when the average response time appears acceptable.
Increased HTTP error rates
An increase in HTTP 429, 500, 502, 503, or 504 responses may indicate rate limiting, application failures, overloaded upstream services, or gateway timeouts.
The status code alone does not identify the cause. Analysts should correlate it with the request pattern and infrastructure state.
Endpoint concentration
Investigate whether traffic is concentrated on specific pages, API routes, search functions, or authentication workflows.
A high request rate to a resource-intensive endpoint may be more damaging than a much larger number of inexpensive cached requests.
Client and session patterns
Review available client metadata, request timing, session behaviour, and distribution across source addresses.
Automated traffic may exhibit repetitive or unusually regular patterns, but legitimate integrations and monitoring systems can behave similarly.
Backend resource pressure
Correlate request activity with CPU, memory, worker utilisation, database latency, connection pools, and queue depth.
This helps determine whether incoming requests are actually causing resource exhaustion.
7. SOC Investigation: A Step-by-Step Workflow
When an alert indicates a possible HTTP flood, use a structured workflow to validate the event and determine its impact.
Step 1: Confirm the affected application
Identify the application, hostname, endpoint, time window, and affected users.
Determine whether the problem affects the entire service or a specific function, such as login, search, or report generation.
Step 2: Review request logs
Collect the available HTTP fields, including:
Timestamp.
HTTP method and path.
Response status code.
Request duration.
Source address, where recorded.
User-agent string.
Request and response sizes.
Request identifier or session information, where available.
Use these fields to identify changes in request volume, endpoint concentration, response behaviour, and request timing.
Step 3: Compare with a normal baseline
Compare the incident period with previous periods that have similar traffic patterns.
Look for abnormal request rates, unusual distributions across endpoints, and differences in error rates or response times.
Account for known business events, software releases, monitoring systems, and legitimate automated clients.
Step 4: Identify the resource bottleneck
Examine CPU, memory, worker utilisation, database connections, request queues, and upstream service latency.
Determine whether the observed requests are exhausting application resources or whether the problem originates elsewhere.
For example, a database connection pool reaching its limit may explain an application's slow responses even when CPU utilisation remains moderate.
Step 5: Correlate network and security telemetry
Review firewall logs, NetFlow, CDN analytics, WAF events, and load-balancer metrics.
Determine whether the HTTP request surge is accompanied by a network-layer attack or whether the main pressure occurs within the application.
Step 6: Assess whether traffic is malicious
Consider the total evidence rather than relying on one characteristic.
Potential supporting evidence includes an abrupt and sustained request surge, unusual endpoint concentration, automated request patterns, disproportionate backend resource use, and service degradation.
No single factor is conclusive. Legitimate clients may generate high request rates, and distributed attacks may resemble ordinary browsing.
Step 7: Apply proportionate mitigation
Coordinate with application owners, network engineers, and DDoS protection providers.
Possible actions include enabling appropriate rate limits, adjusting WAF rules, caching suitable content, restricting abusive traffic patterns, or escalating to upstream protection.
Validate changes carefully to avoid blocking legitimate users.
Step 8: Verify recovery and document the incident
Confirm that request rates, latency, errors, and backend resource consumption have stabilised.
Record the timeline, affected endpoints, evidence, mitigation actions, service impact, and unresolved questions.
8. Practical Example: An HTTP Flood Against an API
Consider an organisation operating an online service with a public search API.
Under normal conditions, the API receives a predictable request rate. During an incident, the API gateway reports a sudden increase in requests, while database connection usage and p95 latency rise sharply.
Network monitoring shows that bandwidth remains below the organisation's available capacity.
The initial evidence suggests that the problem may be application-layer resource exhaustion rather than a volumetric network flood.
The SOC investigates:
Request distribution: The team identifies an unusual concentration of requests against the search endpoint.
Response behaviour: The endpoint begins returning more 5xx errors and taking longer to respond.
Backend pressure: Database connections and query latency rise at the same time.
Client patterns: The team identifies several unusual traffic patterns, but does not rely on source IP addresses alone.
Mitigation: Application owners introduce an appropriate rate limit and improve caching for eligible search requests.
Validation: Latency, connection usage, and error rates return towards normal levels.
This example illustrates how an HTTP flood can disrupt a service without saturating its network link.
It also demonstrates the importance of correlating application and infrastructure metrics before deciding which mitigation to apply.
9. Detection Engineering and SIEM Monitoring
SOC teams can develop detections using web server logs, API gateway events, WAF telemetry, and application performance metrics.
Useful detection features include:
Request rate by endpoint over short intervals.
Changes in p95 or p99 latency.
Error-rate increases.
Repeated requests associated with high backend resource consumption.
Unusual request distribution across clients or sessions.
Simultaneous increases in request queues or database connection usage.
Example Splunk query
The following is an illustrative starting point for web logs that contain the fields clientip, uri_path, and status. Replace the index and field names with those used in your environment.
index=web earliest=-30m
| bin _time span=1m
| stats count AS requests
dc(clientip) AS unique_clients
by _time uri_path
| sort _time
This query calculates the number of logged requests and distinct client addresses per endpoint per minute. It does not establish whether the requests are malicious.
To make the detection more useful, compare the resulting metrics with endpoint-specific baselines and correlate them with latency, error rates, and backend resource utilisation.
Distinct client counts should also be interpreted cautiously because of NAT, proxies, CDNs, and distributed traffic sources.
Building a more reliable alert
A stronger detection combines multiple signals:
Request rate is significantly above the normal baseline.
Traffic is concentrated on a particular endpoint or service.
Latency, errors, or backend resource usage deteriorate.
The pattern cannot be readily explained by known legitimate activity.
The exact thresholds should be tuned to the application and tested against normal traffic to minimise false positives.
10. Mitigation Strategies for HTTP Flood Attacks
Content delivery networks
A CDN can absorb traffic, distribute requests, and cache eligible content closer to users.
Caching is especially useful for public content that does not require personalised backend processing. It is less effective for dynamic operations that must be executed for every request.
Web application firewalls
A WAF can inspect HTTP requests and apply rules based on request attributes, known abuse patterns, and configured security policies.
A WAF should be tuned carefully. Broad rules can block legitimate traffic, while rules that inspect only obvious signatures may miss distributed attacks using valid requests.
Rate limiting
Rate limits can restrict excessive requests by client, session, account, endpoint, or other application-specific attributes.
The appropriate key depends on the service. IP-based limits alone can affect many legitimate users behind shared networks and may be less effective against distributed traffic.
Caching and application optimisation
Cache suitable responses, optimise expensive queries, and avoid unnecessary work during request processing.
Where possible, impose sensible limits on request size, execution time, concurrency, and resource-intensive operations.
Backend protection
Use connection-pool limits, queue controls, timeouts, and circuit breakers where appropriate to prevent one overloaded component from exhausting the entire application.
These controls should be designed carefully so that they protect the service without creating cascading failures.
Upstream DDoS protection
If the HTTP flood is part of a broader attack or overwhelms the available infrastructure, use CDN-based or specialised DDoS mitigation services to filter traffic before it reaches the origin.
Ensure that the origin server cannot be accessed through an unprotected route that bypasses the intended mitigation architecture.
11. Common Analyst Mistakes
Assuming high request volume proves an attack. Legitimate traffic surges and automated integrations can produce similar patterns.
Monitoring bandwidth alone. Application resources may be exhausted while network utilisation remains moderate.
Blocking every unfamiliar client. New or uncommon clients are not automatically malicious.
Treating all HTTP errors as attack indicators. Errors may originate from application defects, upstream failures, or intentional rate limiting.
Ignoring expensive endpoints. A small number of resource-intensive requests can create more damage than a much larger number of inexpensive requests.
Applying rate limits without testing. Poorly tuned controls may deny access to legitimate users.
Stopping the investigation after traffic decreases. Confirm that backend services recover and check for continuing or changing attack patterns.
12. MITRE ATT&CK Mapping
The following techniques may apply depending on the observed behaviour and the resources affected.
TechniqueIDRelevanceNetwork Denial of ServiceT1498Applies when network traffic overwhelms network capacity or availabilityEndpoint Denial of ServiceT1499Applies when an endpoint's resources are exhaustedApplication Exhaustion FloodT1499.003Relevant when application requests exhaust service resources
An HTTP flood that exhausts application workers or backend resources may align with application exhaustion. However, the mapping should reflect the actual behaviour rather than the HTTP protocol alone.
Conclusion
HTTP flood attacks demonstrate that application availability can be disrupted without overwhelming the network connection itself. By generating excessive requests, attackers can exhaust web-server workers, CPU, memory, database connections, and other resources required to process legitimate transactions.
For SOC analysts, effective detection depends on correlating request rates with endpoint behaviour, response latency, error rates, and backend resource consumption. Network telemetry adds useful context, but application-level visibility is essential for understanding the impact.
A resilient defence combines CDN protection, WAF controls, carefully designed rate limits, caching, application optimisation, backend safeguards, and tested incident-response procedures.
The key lesson: Detecting an HTTP flood is not simply about counting requests. It is about understanding how those requests consume resources and whether they prevent legitimate users from accessing the service.